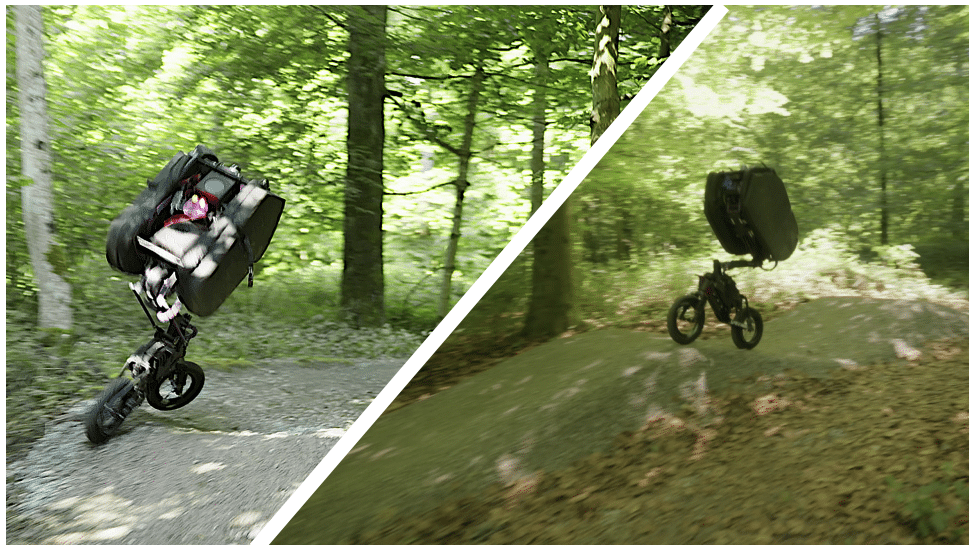
We show that autonomous, high-speed trail navigation can be achieved through a single idea: encoding the trail as a semantic layer of the terrain.
Resources
By Topic:
By Type:
CoRL 2026 Publication and Workshop Round Up
Research teams at the RAI Institute had several papers and workshops accepted for CoRL 2026, covering topics such as handheld data collection, loco-manipulation, robot mapping...
Sceniris: A Fast Procedural Scene Generation Framework
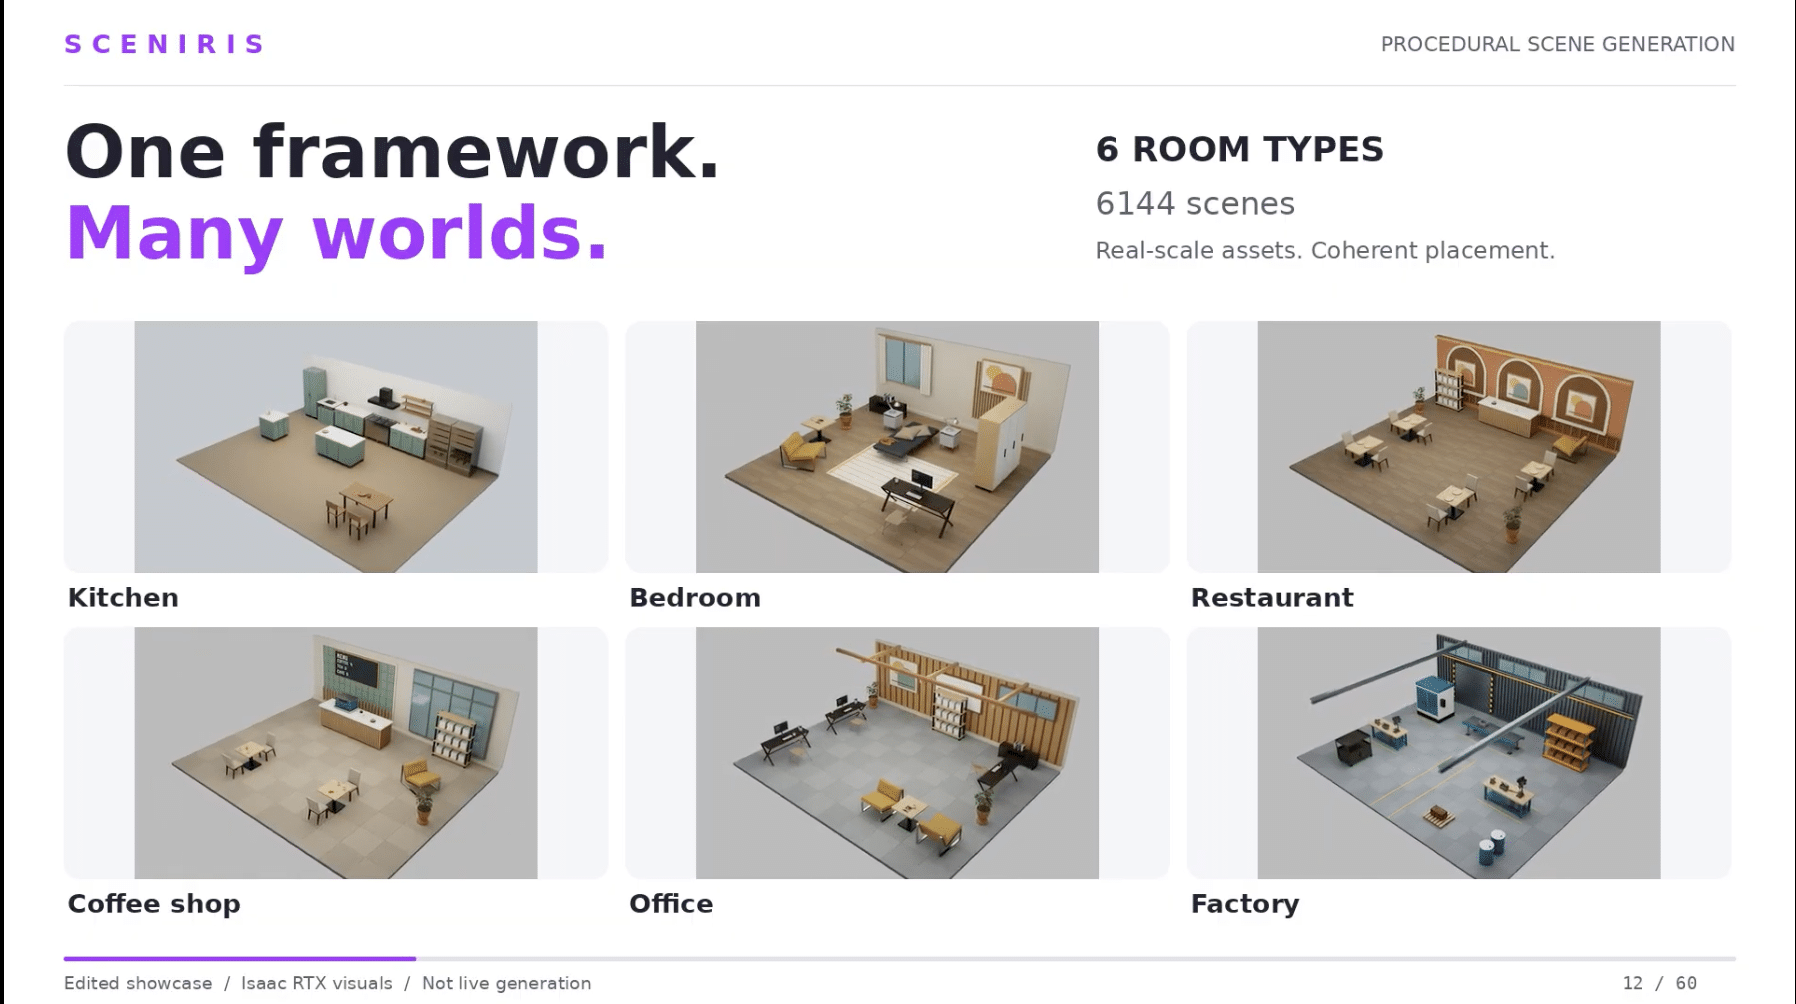
We introduce Sceniris, a highly efficient procedural scene generation framework for rapidly generating large-scale, collision-free scene variations.
Bridging Handheld and Teleoperated Supervision for Contact-Rich Manipulation via State-Gated Experts
We propose Bi-modal Routing for Imitation Data via Gated Experts (BRIDGE), a mixture of diffusion policy experts that routes between specialist heads conditioned on the...
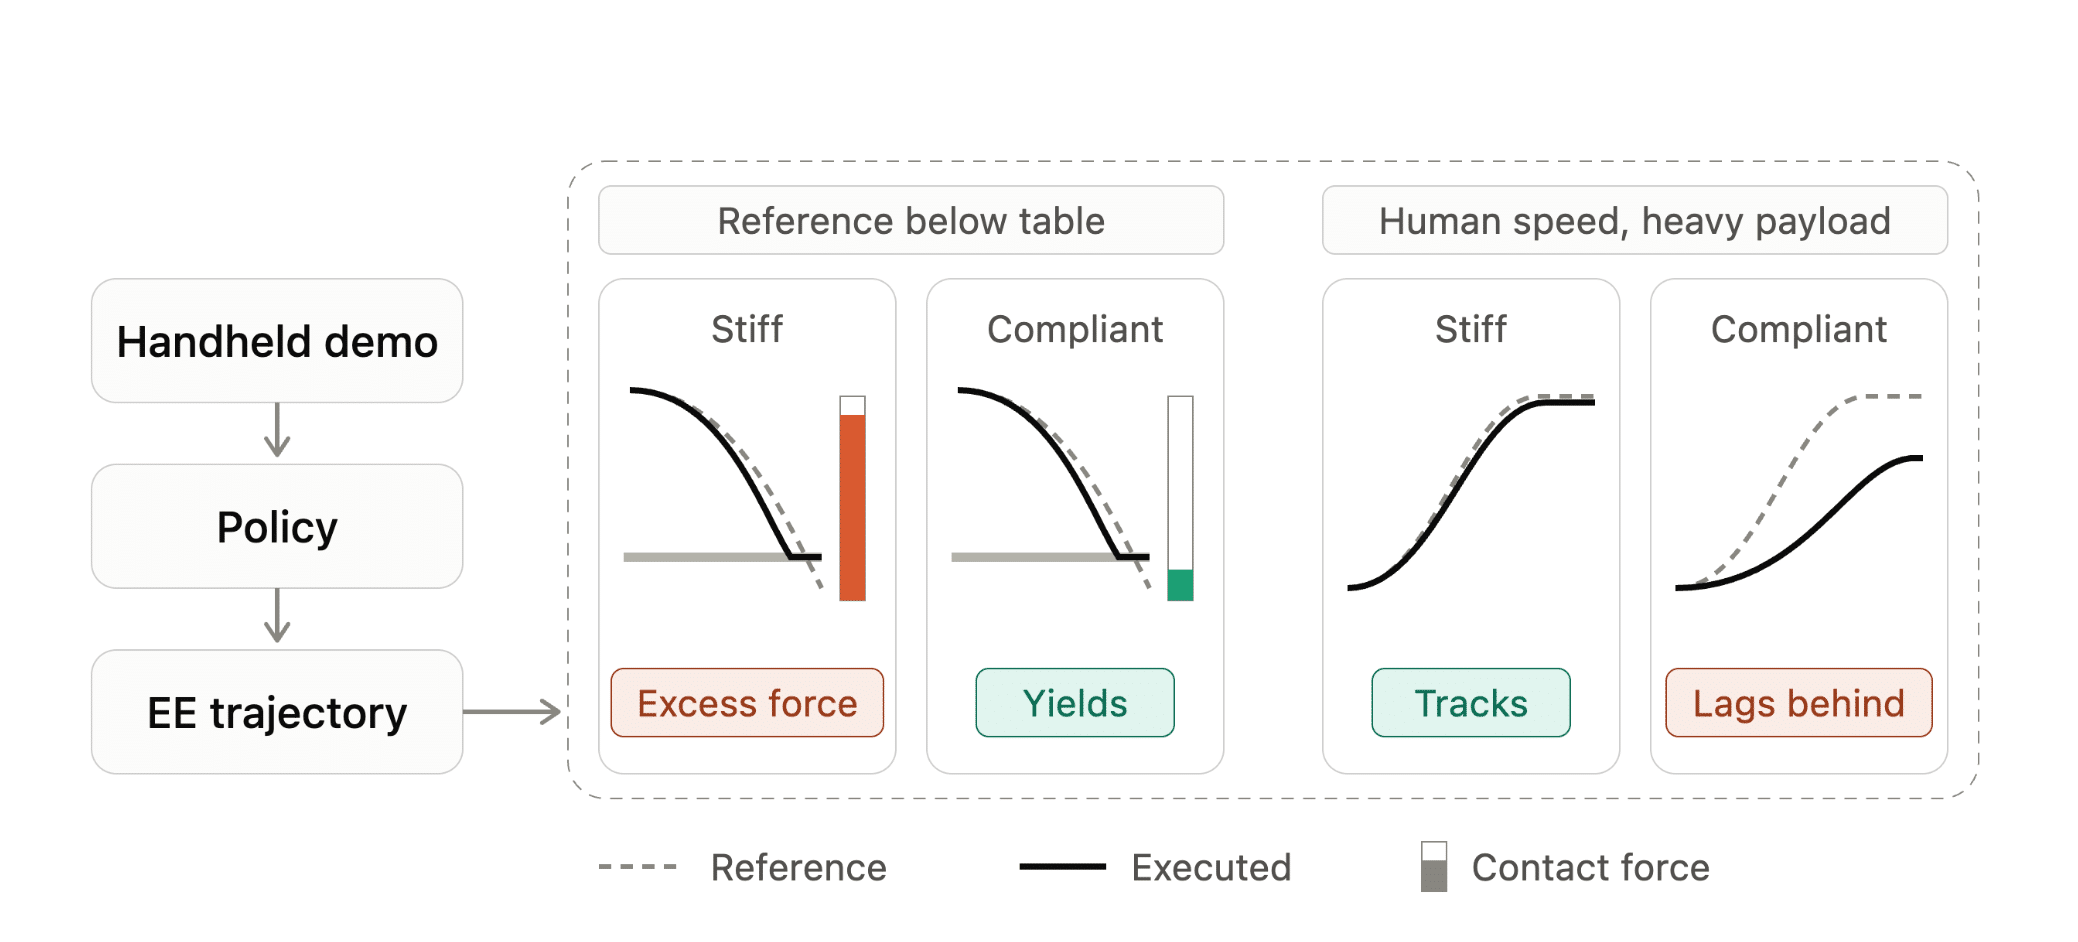
An Empirical Analysis of Controller Selection for Safe Execution of UMI-Style Policies
Current policy evaluation protocols often conflate policy and execution errors by treating the robot controller as a fixed implementation detail. By testing various controllers across...
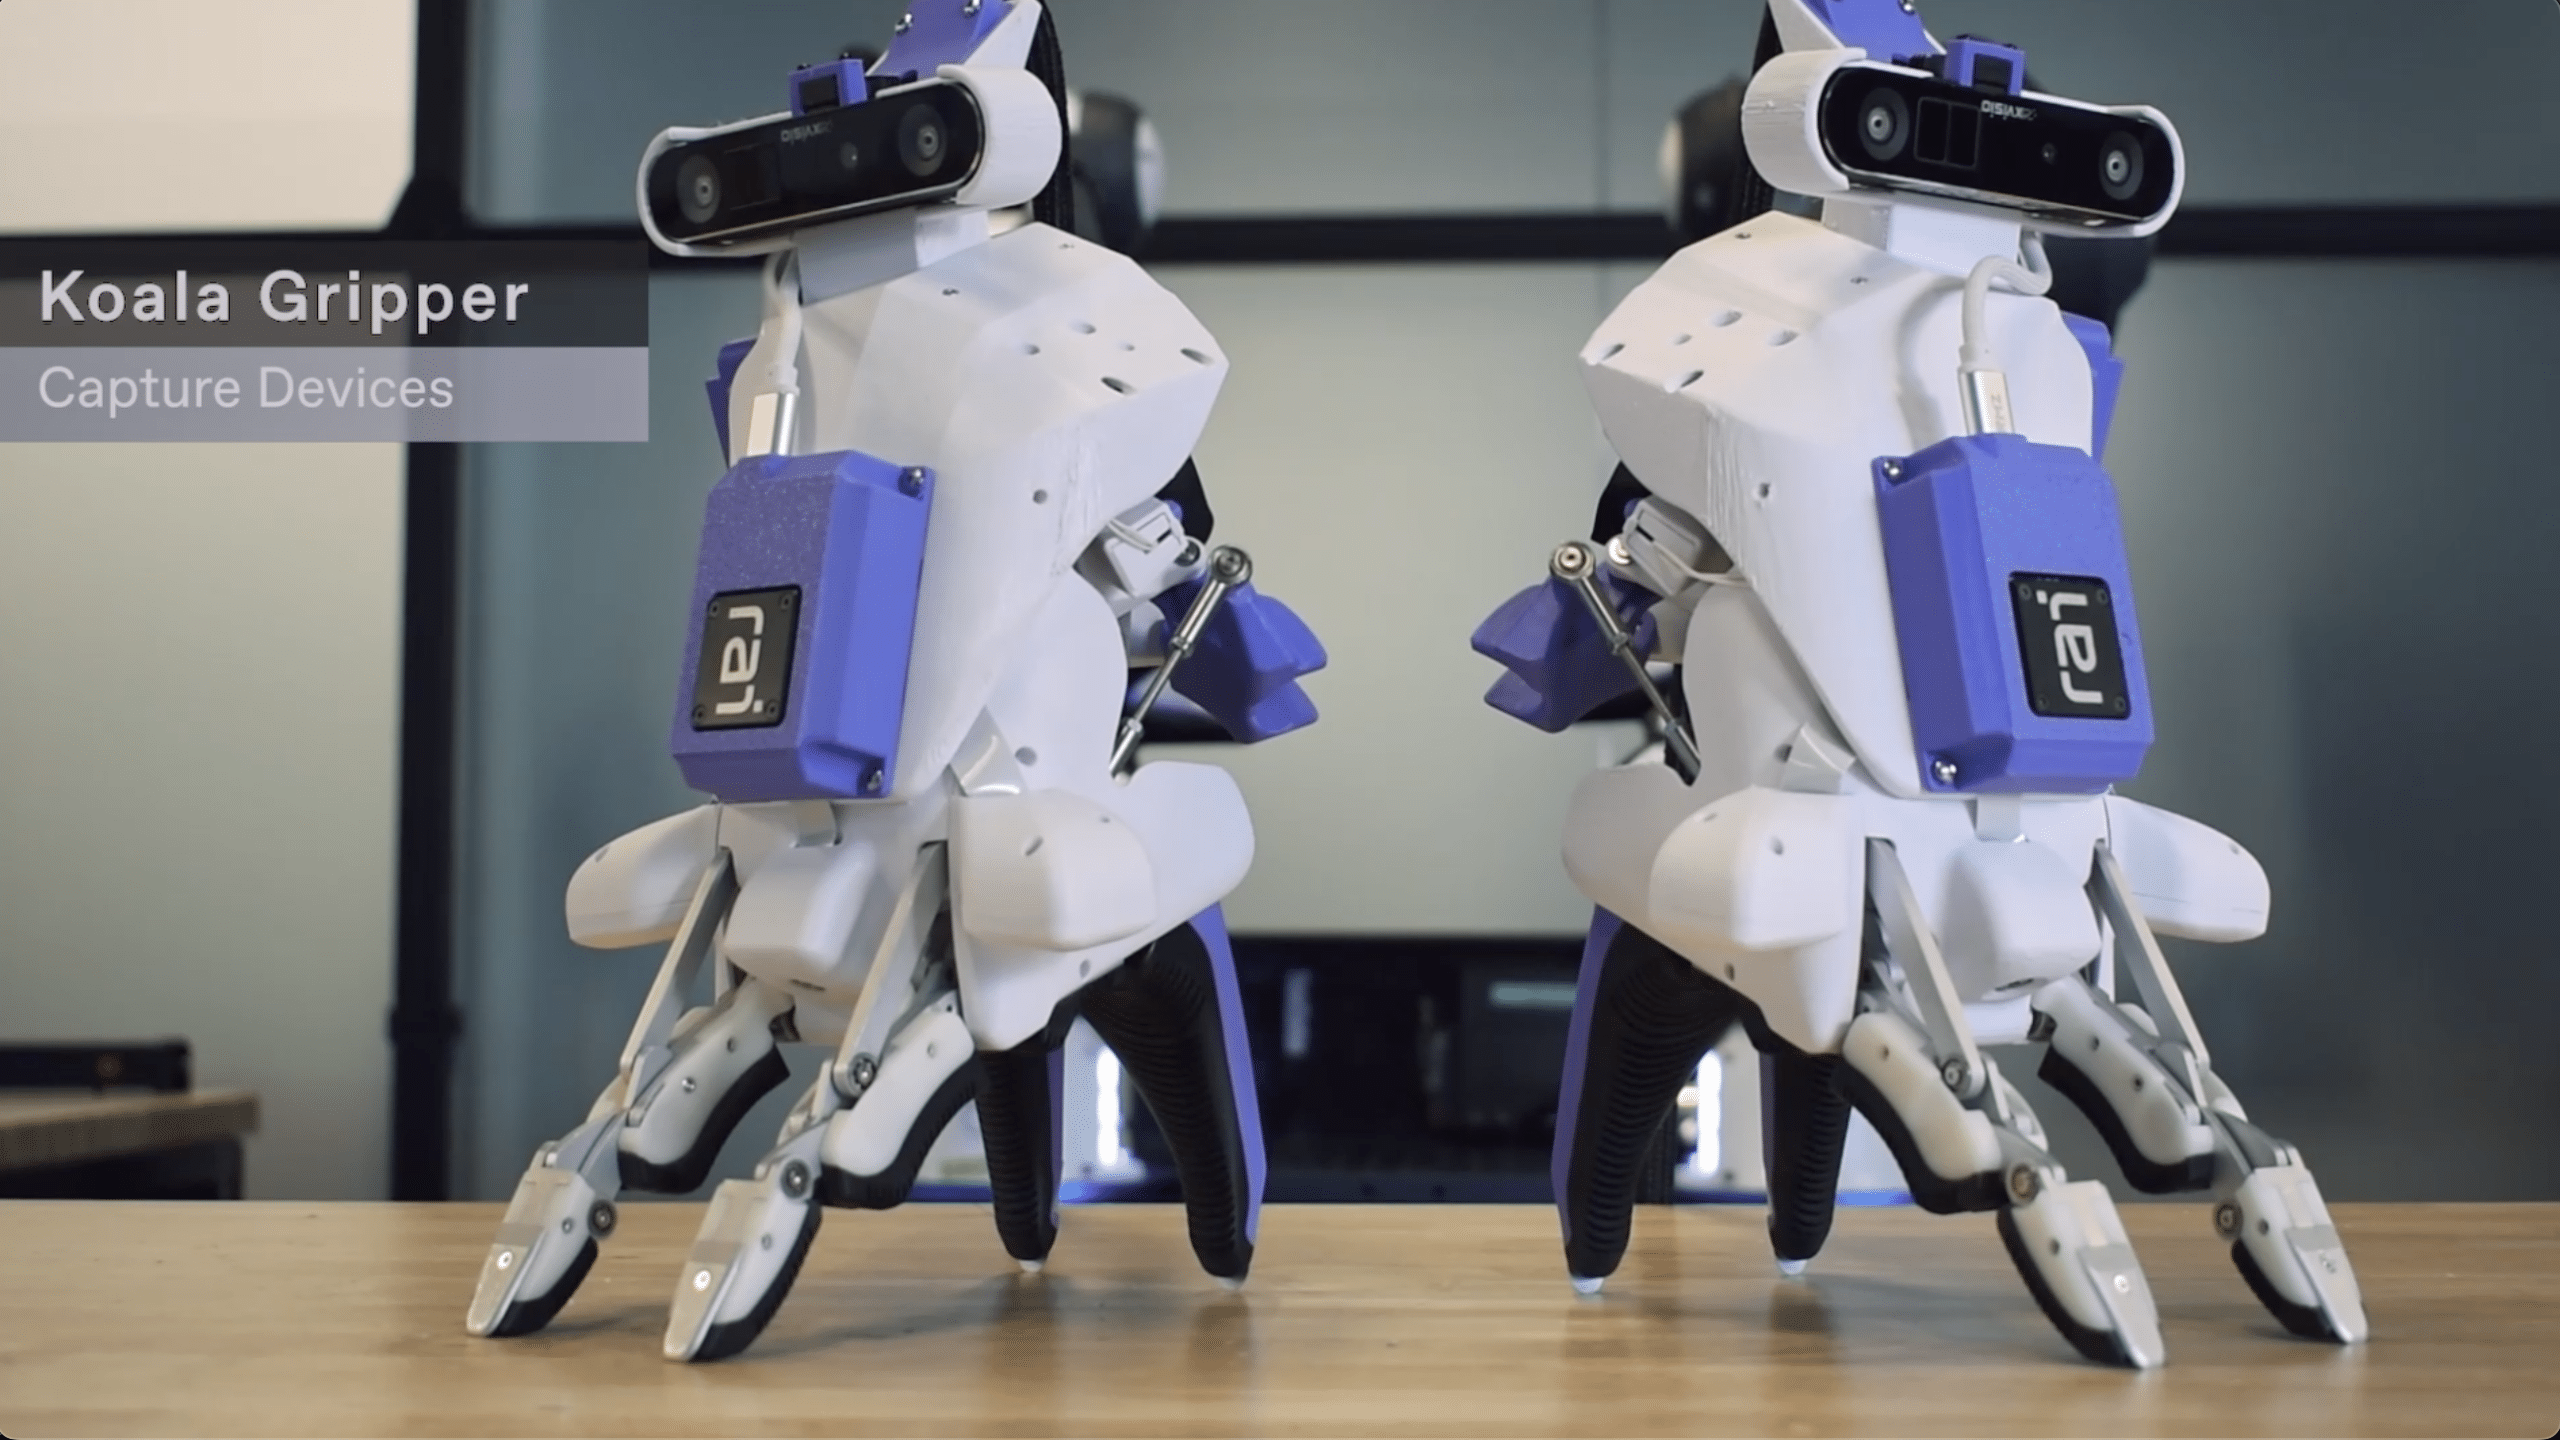
Koala Gripper: Co-designing Robotic Grippers and Data Capture Devices for Scaling Dexterous Manipulation Learning
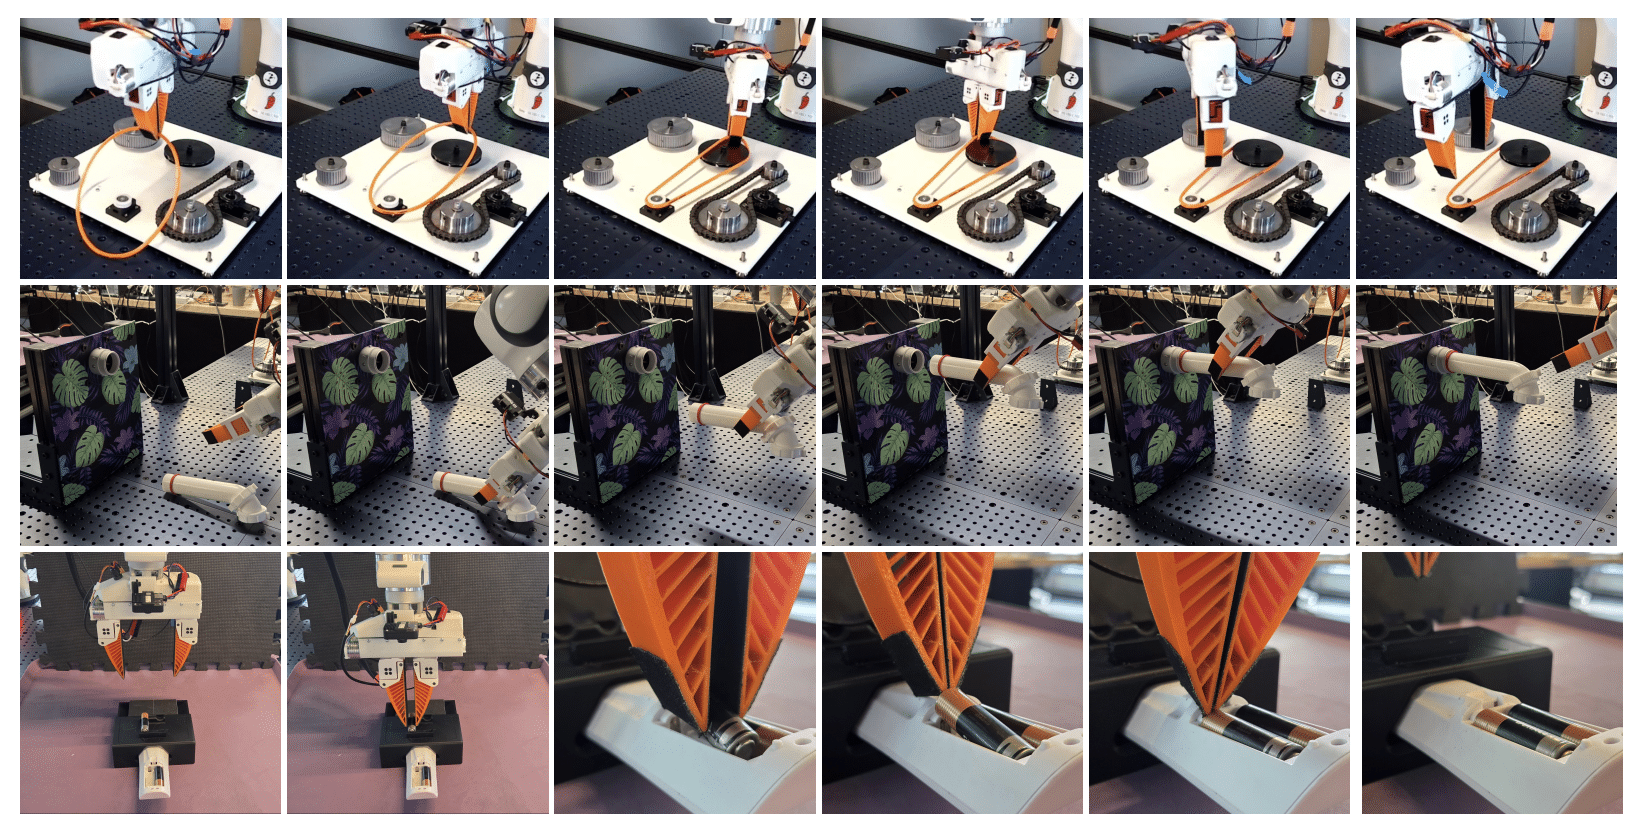
We present the Koala Gripper system, a data capture device and robotic gripper platform that improves dexterity and grasp capability compared to parallel jaw grippers...
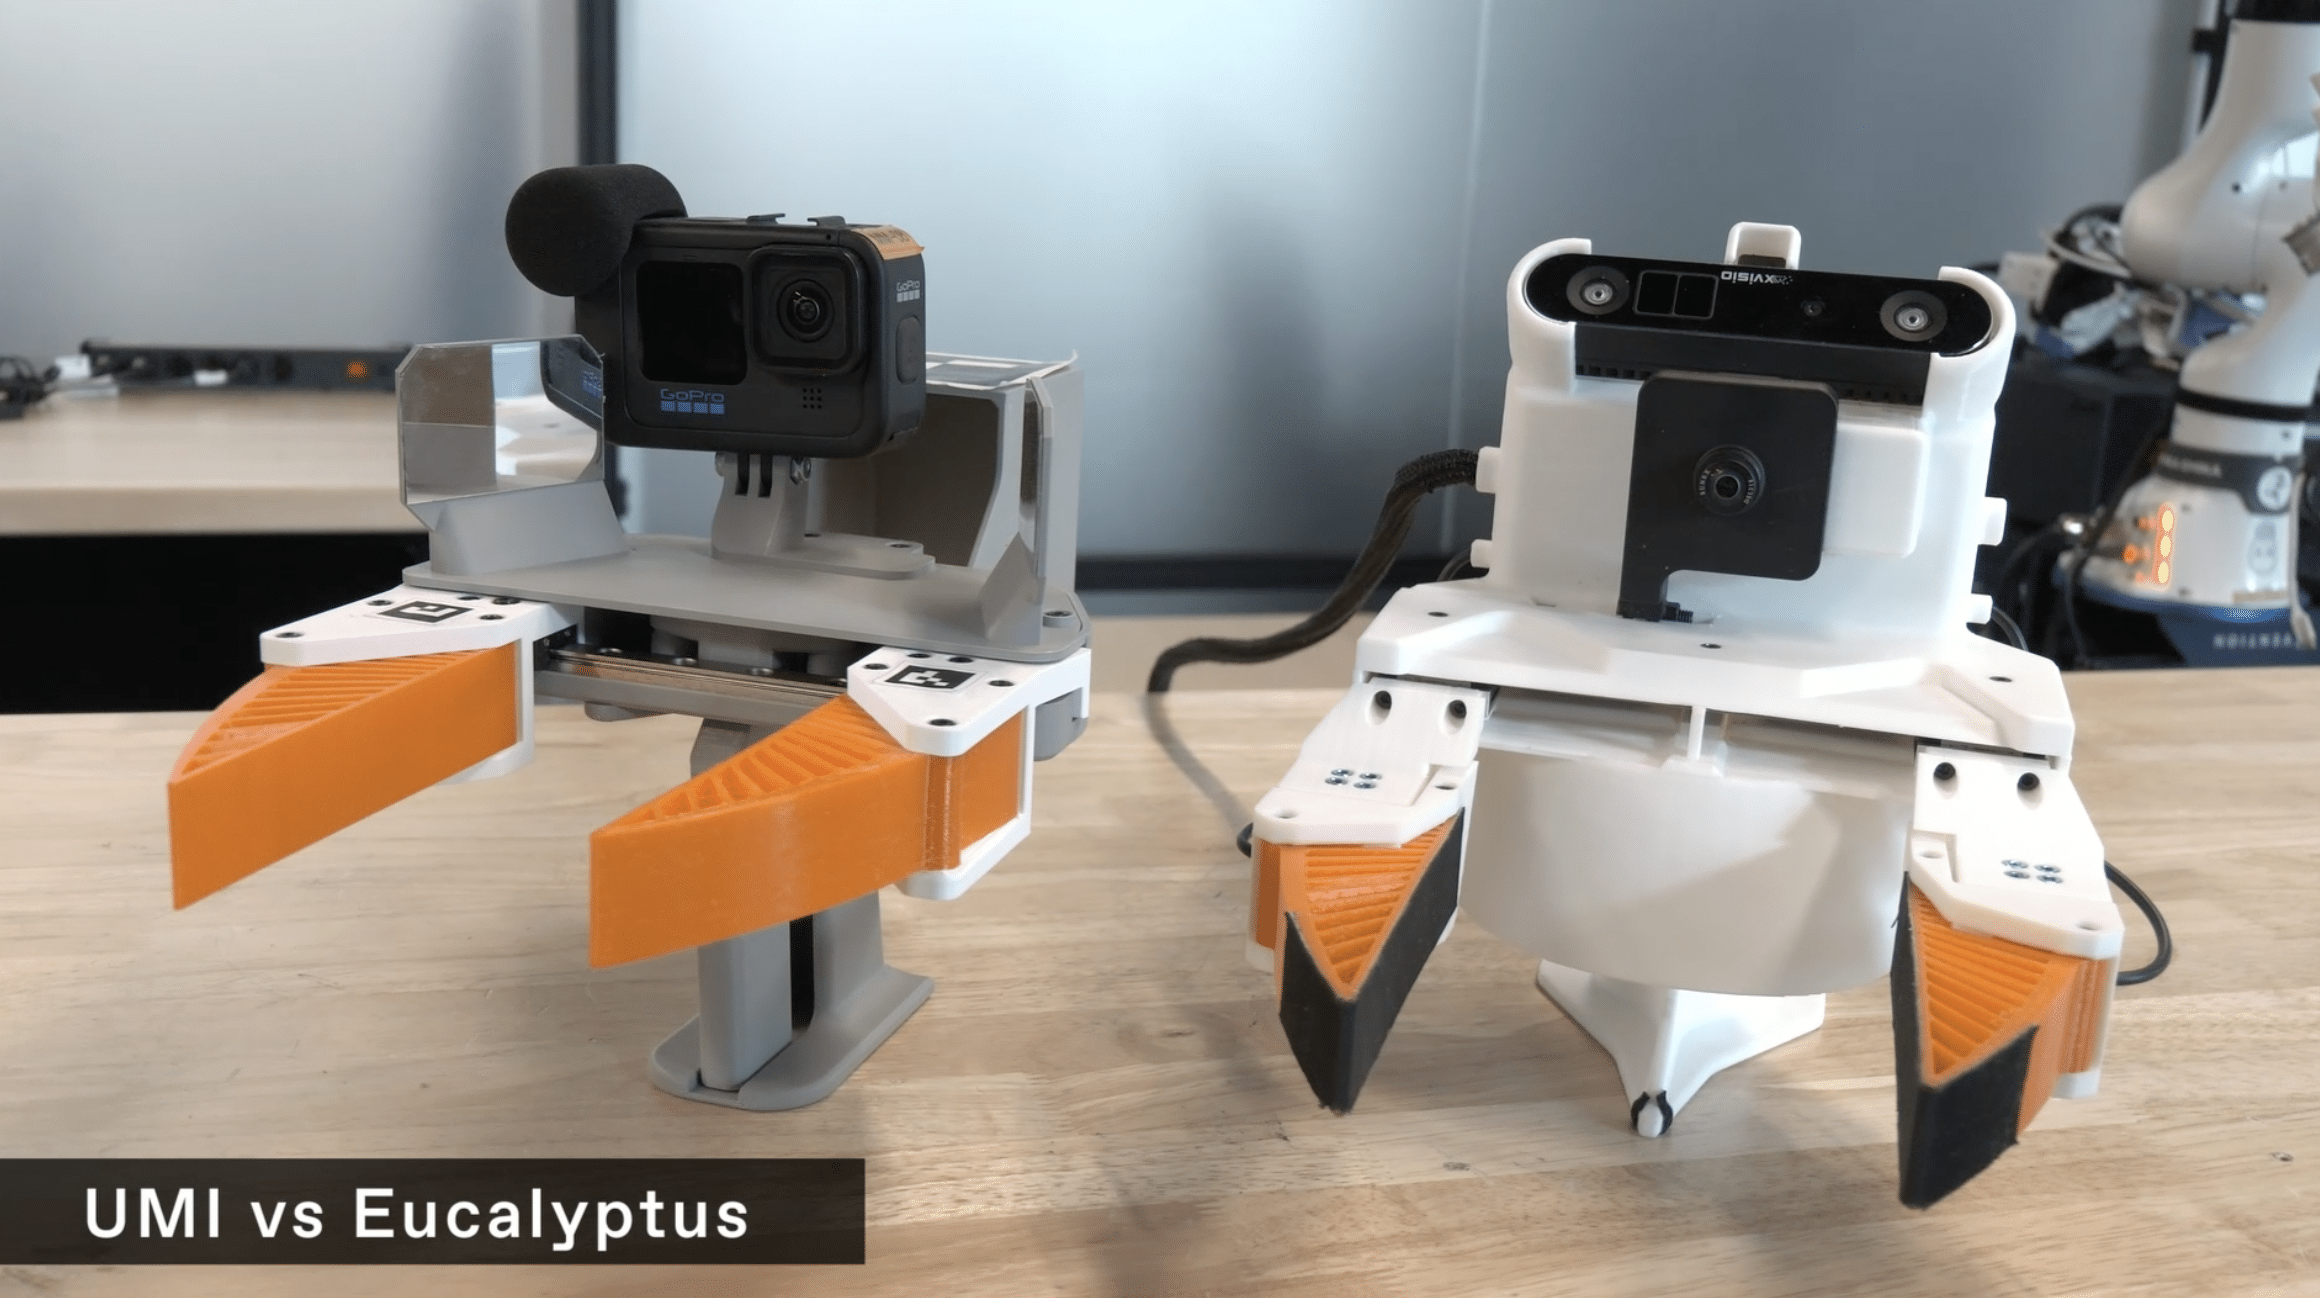
Eucalyptus: A High-Fidelity Multimodal UMI
We present Eucalyptus, an extension of UMI designed for sustained, force-aware data collection. Eucalyptus combines a robustified and ergonomics-oriented mechanical design with a high-fidelity multimodal...
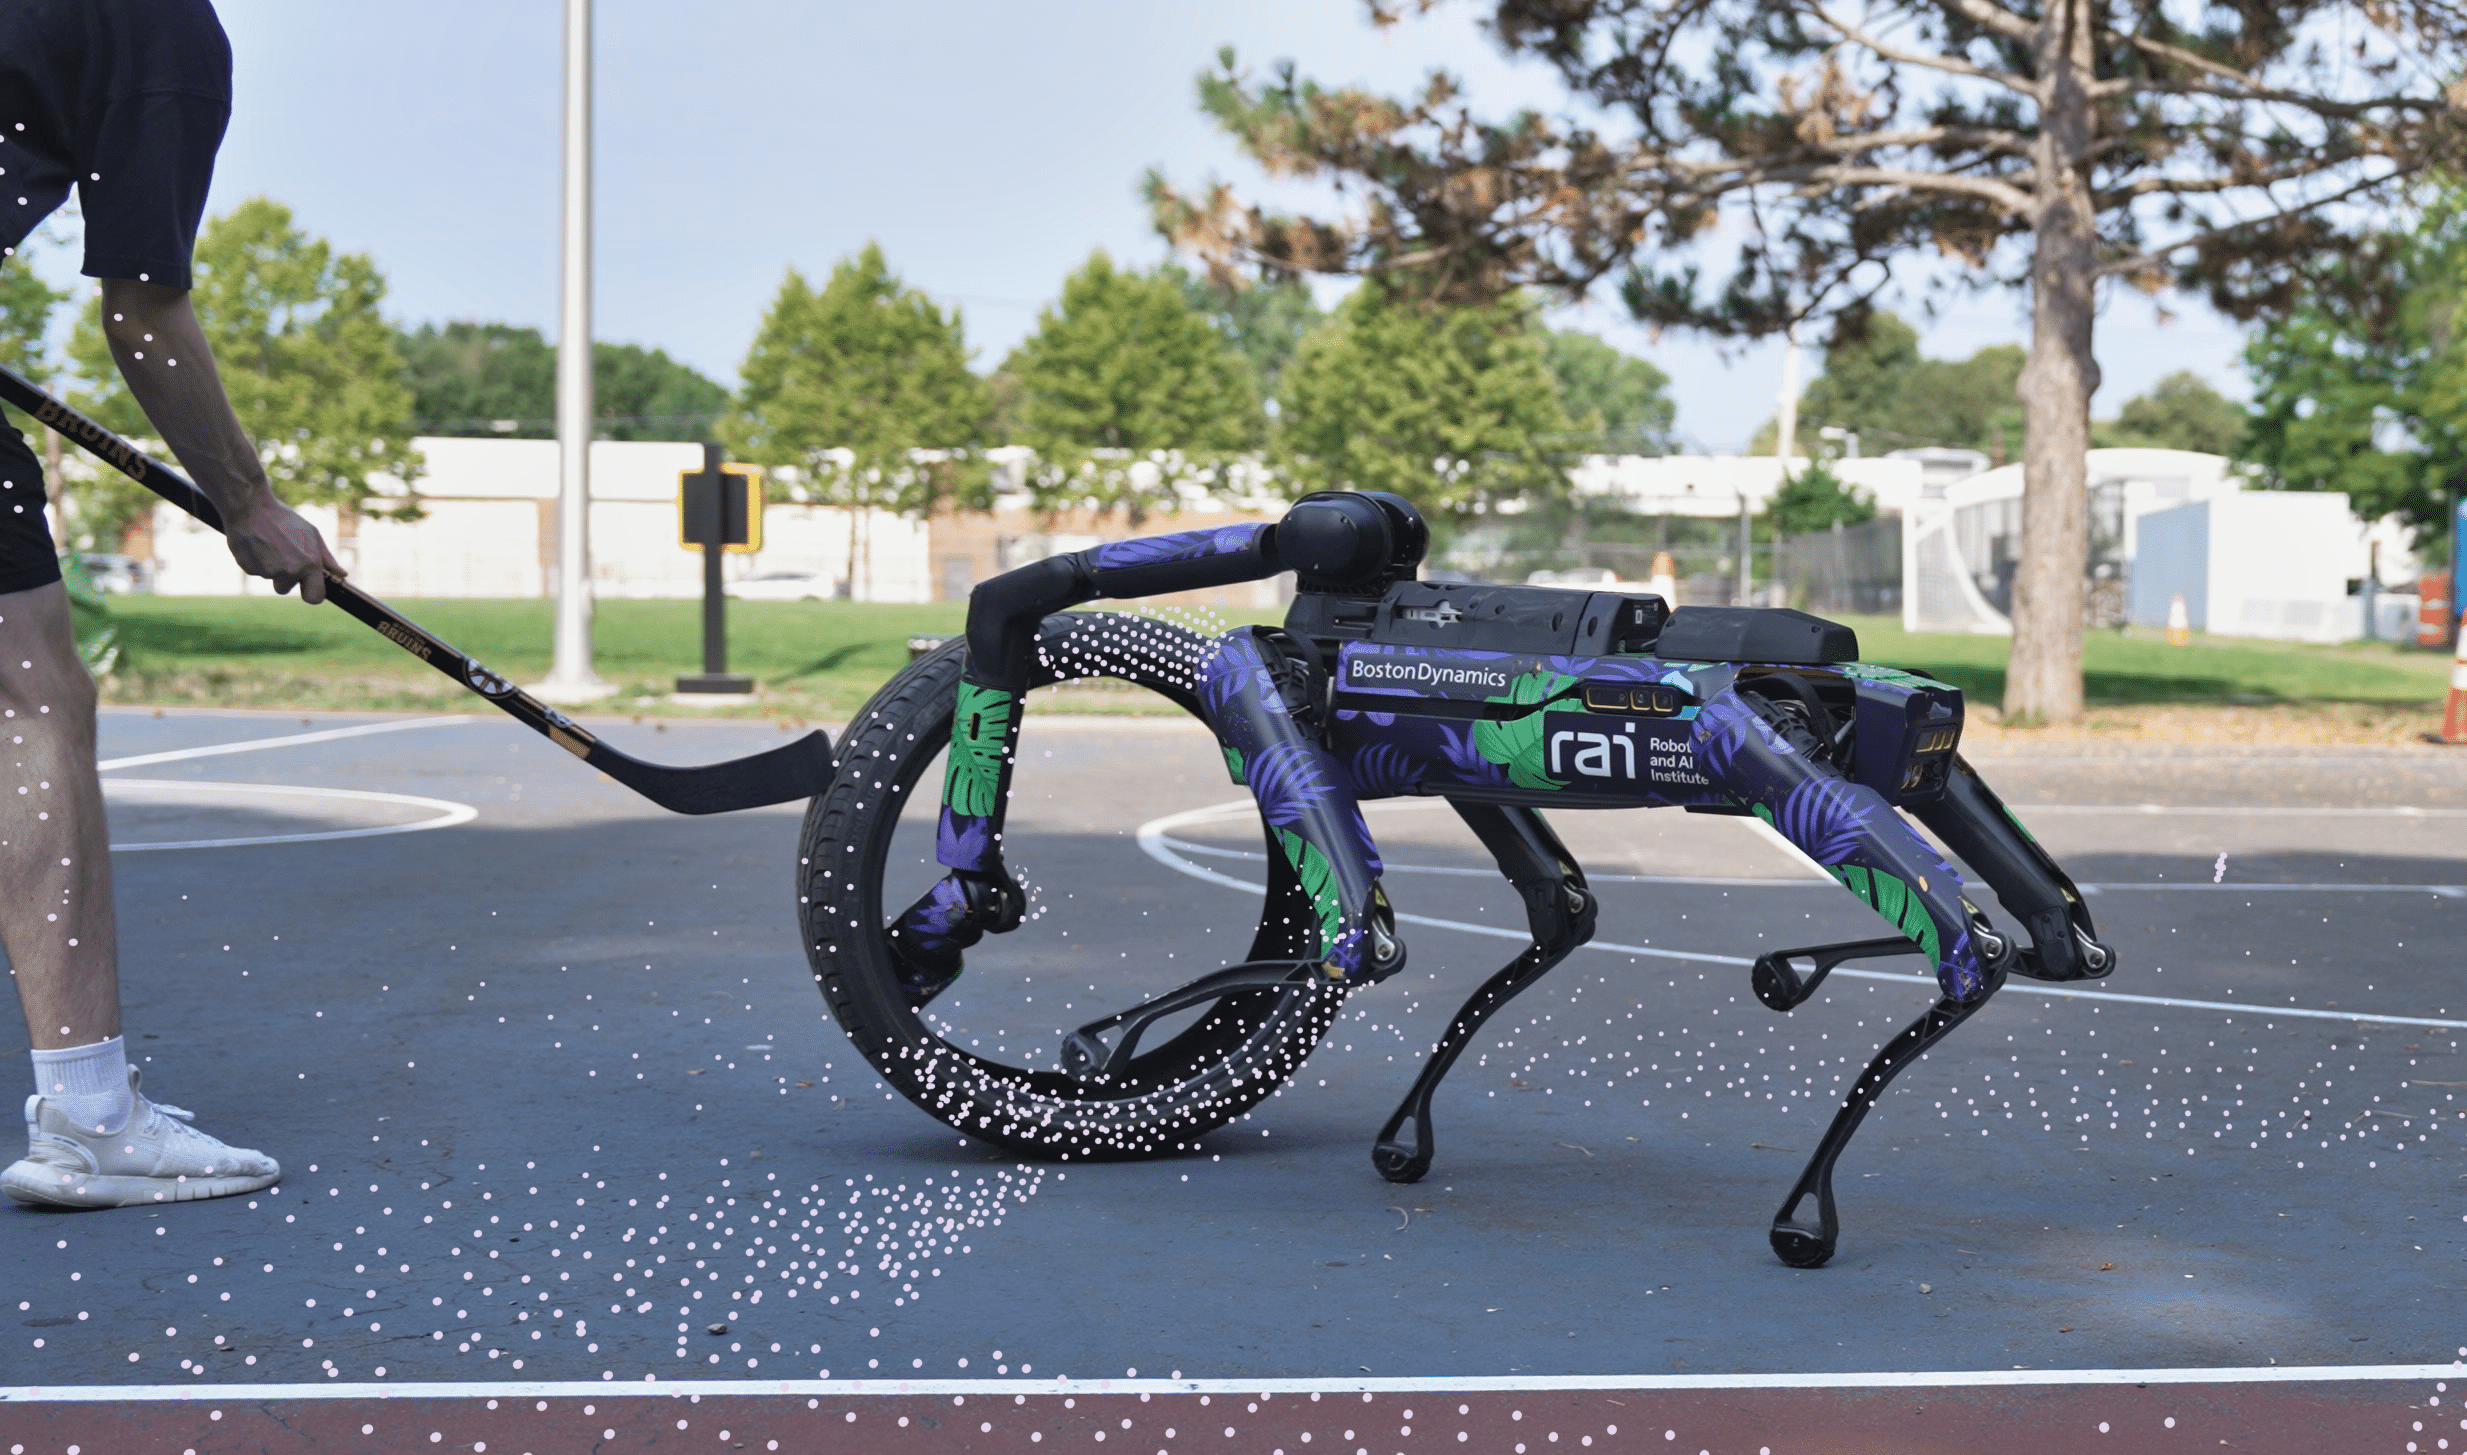
Perceptive Dynamic Manipulation with Spot
By replacing external motion capture with onboard depth-camera perception and local policy evaluation, we can achieved full autonomy and untethered outdoor execution to perceive, locate,...
Whole-Body Manipulation Outside the Lab
Spot performs dynamic manipulation outside the lab using onboard depth cameras and a computer.
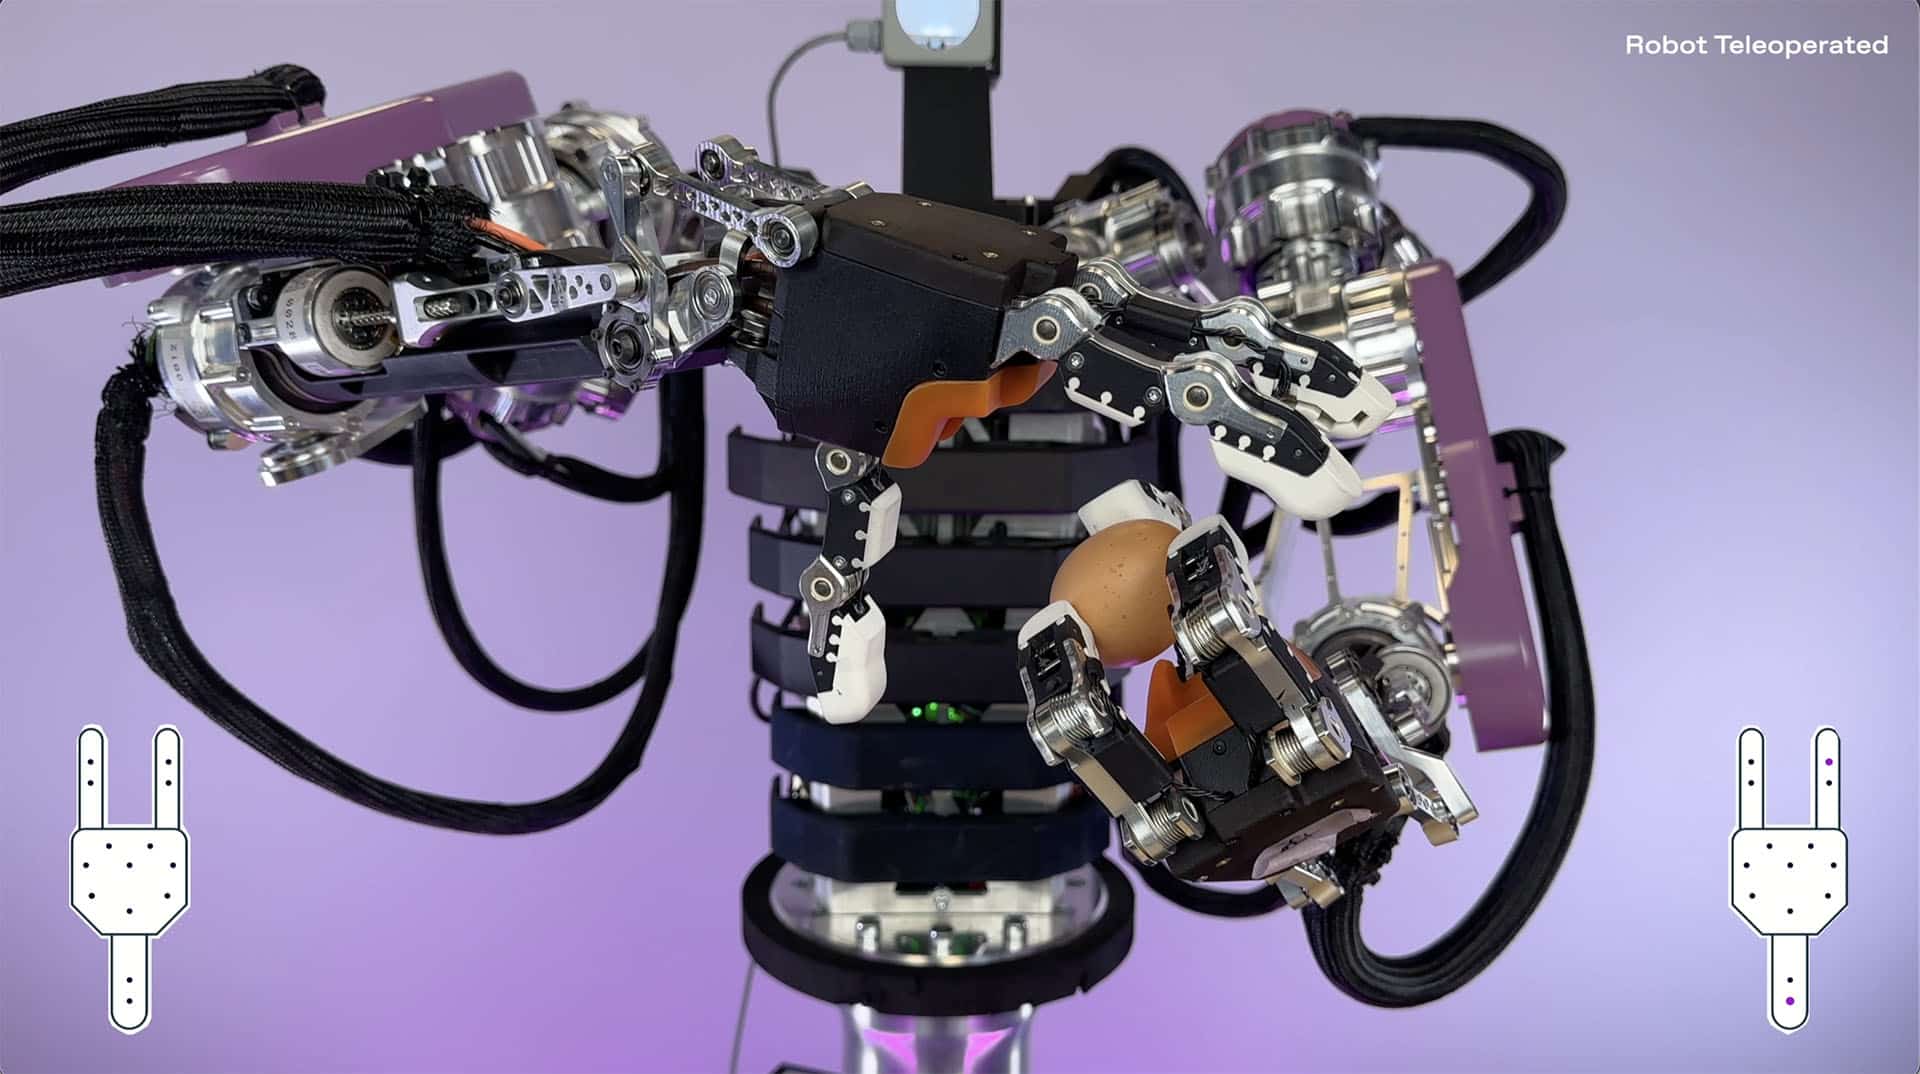
Hardware Spotlight: AthenaZero Tactile Sensing
To perform tasks that require forceful manipulation and delicacy with a single robot design requires not only a powerful robot but also smart control. Providing...
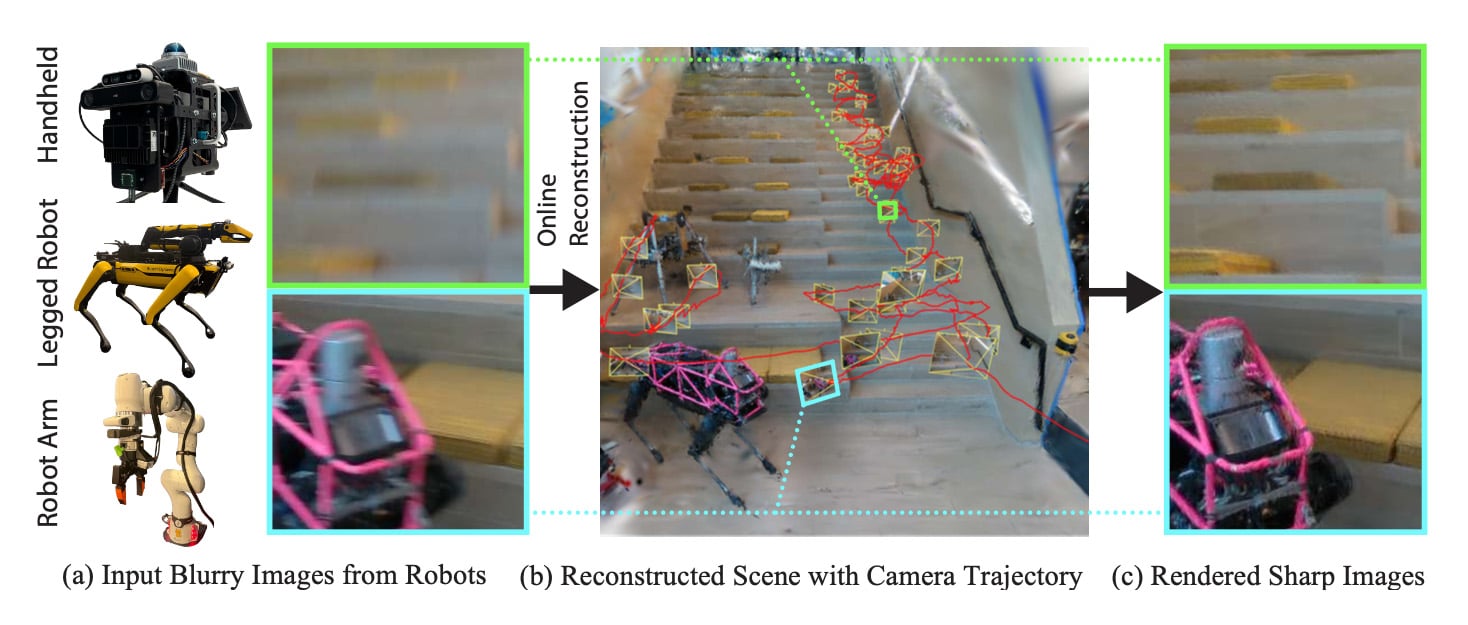
RoMo-GS: Efficient Online 3D Gaussian Splatting for Robot Mapping via Exposure-Integrated Motion Blur
We present RoMo-GS, an online 3DGS system. Instead of averaging N discrete sub-frames as in prior motion blur-aware 3DGS, we analytically integrate each projected Gaussian...
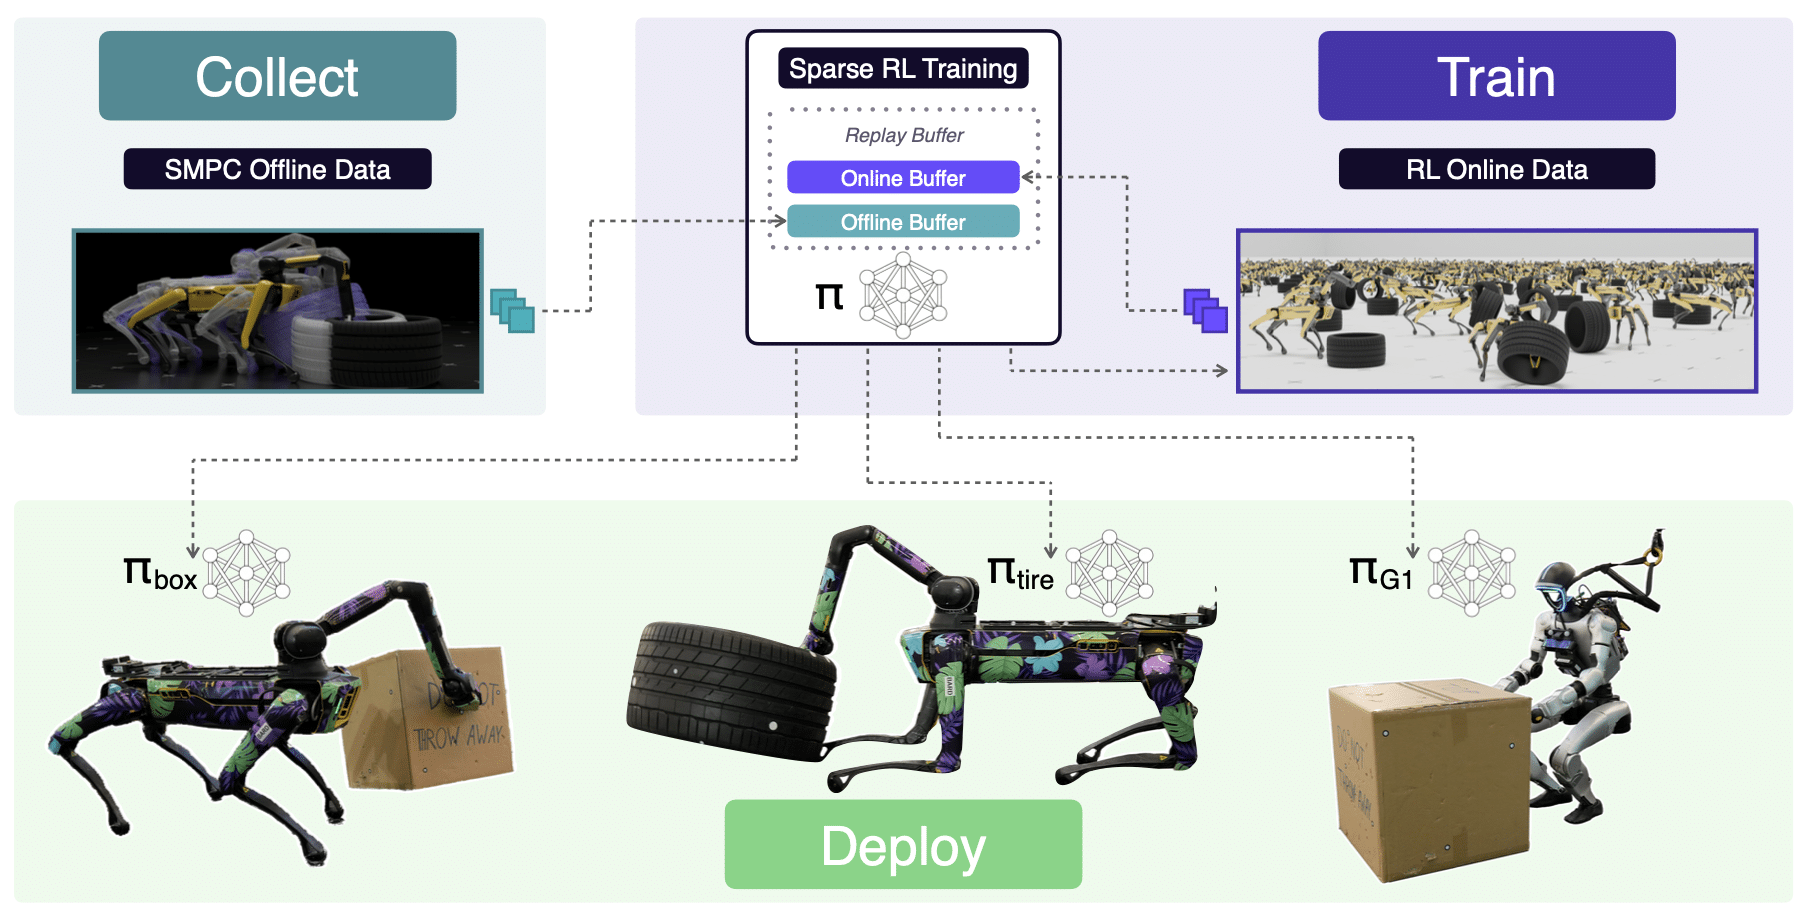
Learning Loco-Manipulation From SMPC Demonstrations With Sparse Offline-to-Online RL
Integrating locomotion and manipulation is essential for robot autonomy, but scaling standard Reinforcement Learning (RL) to complex tasks is severely bottlenecked by the slow, manual...