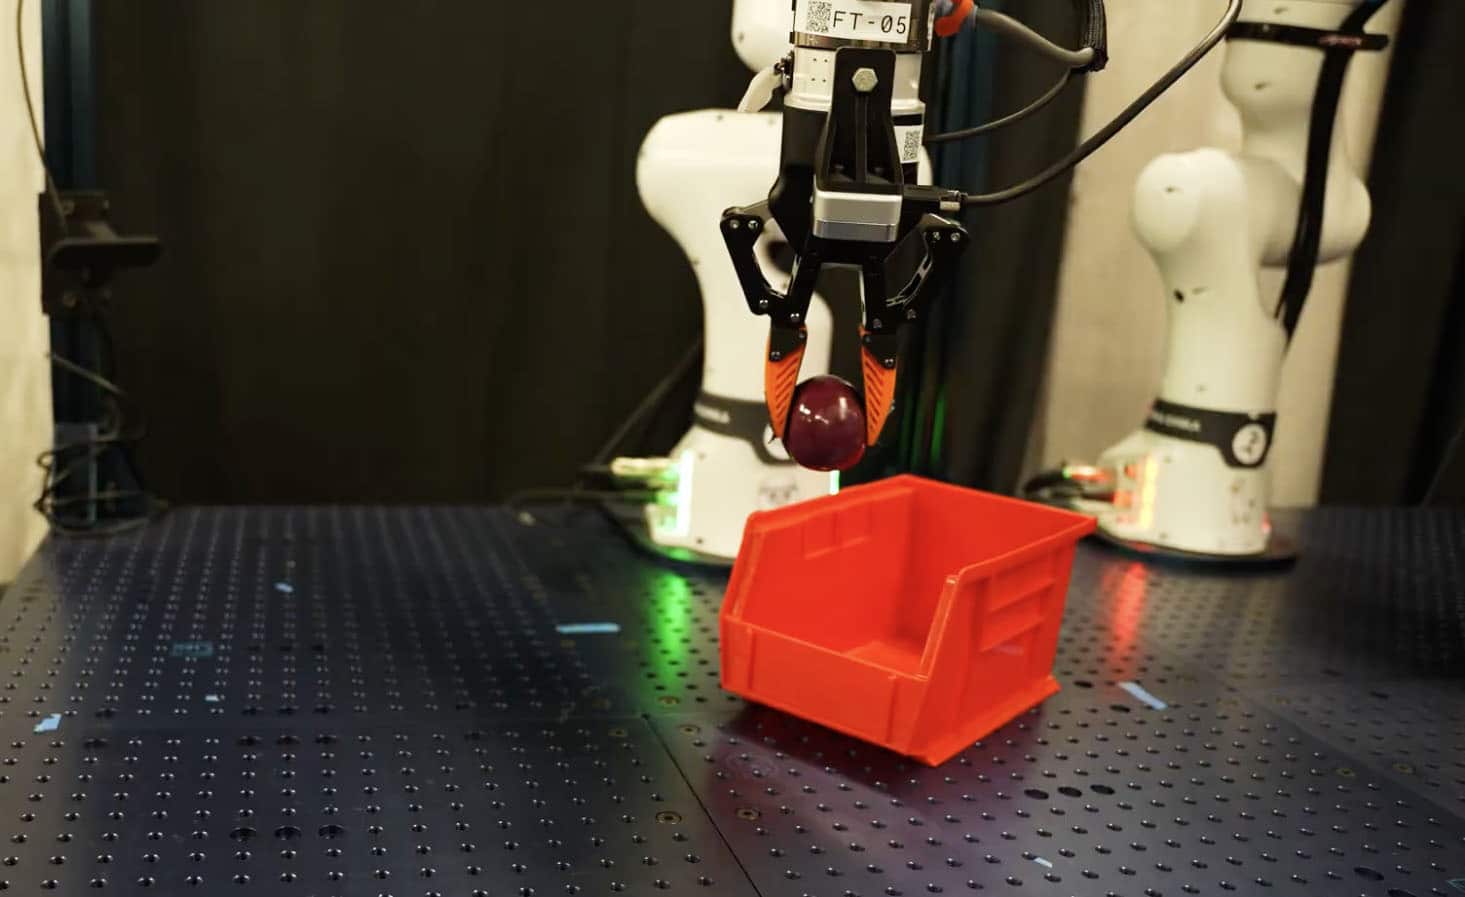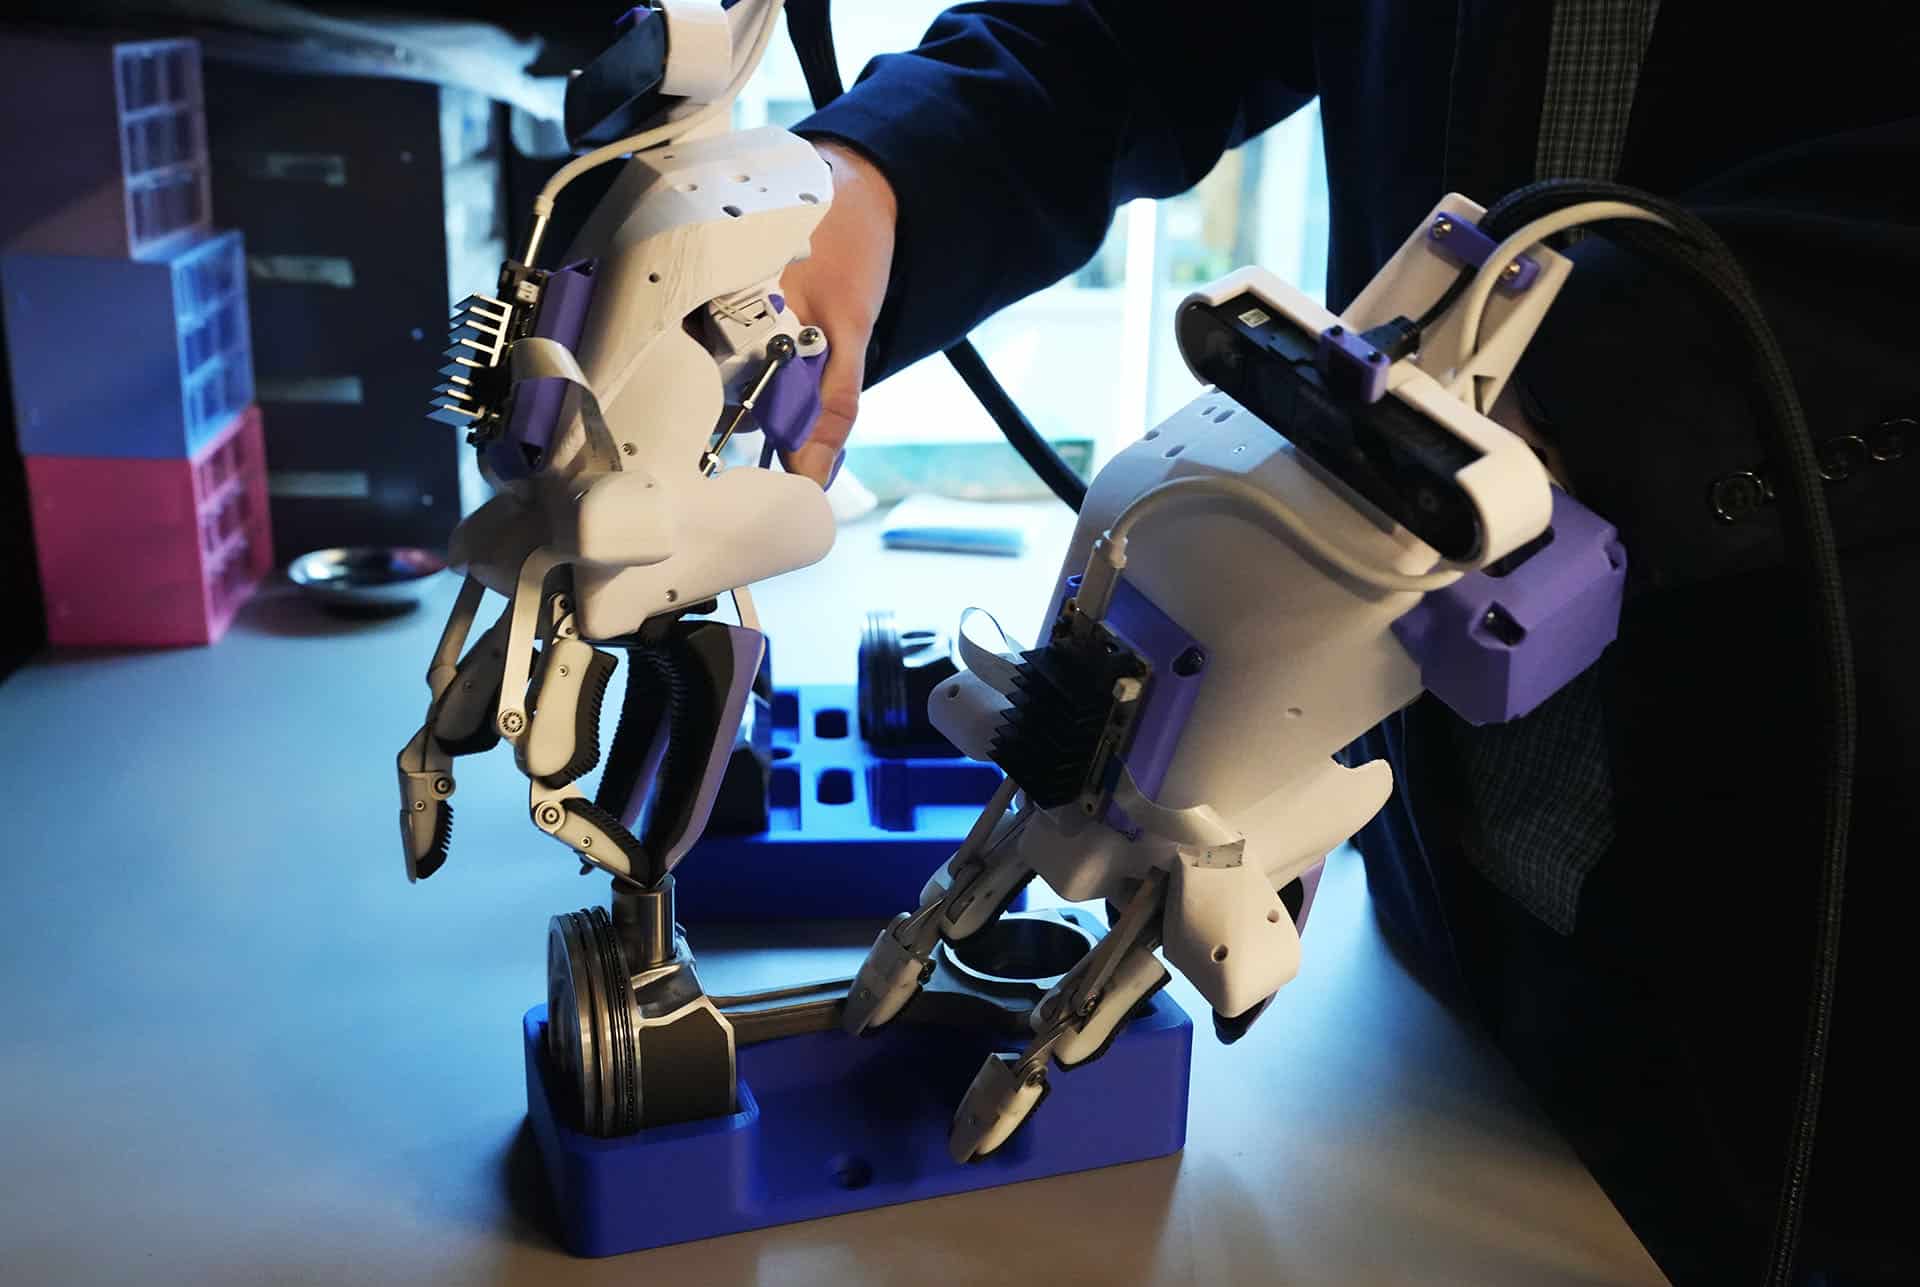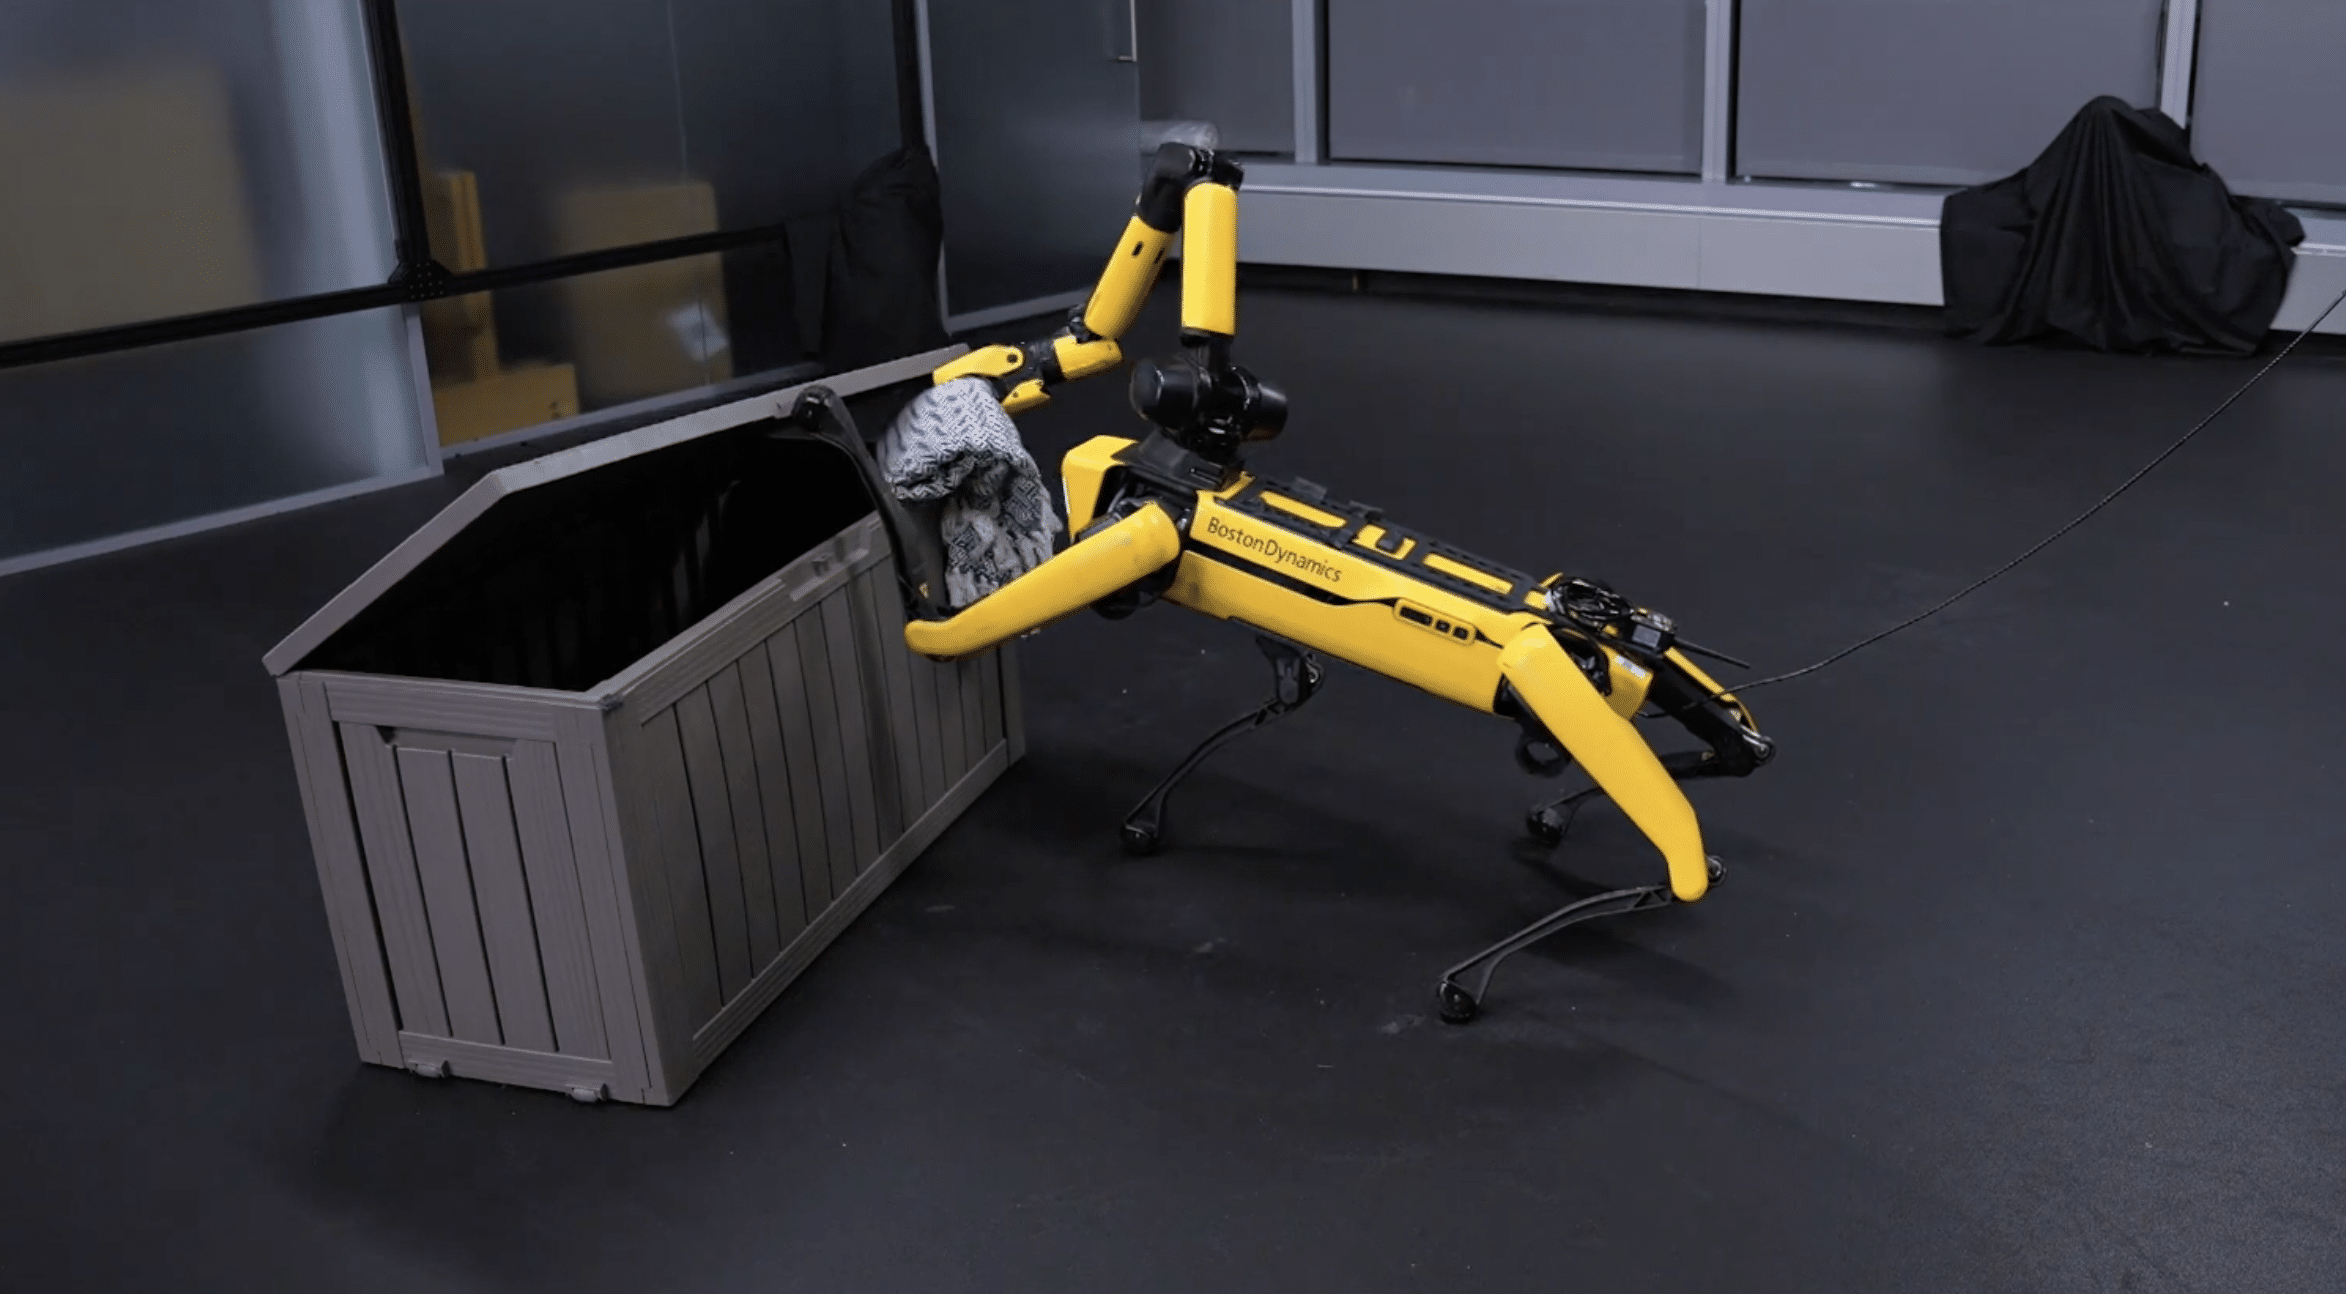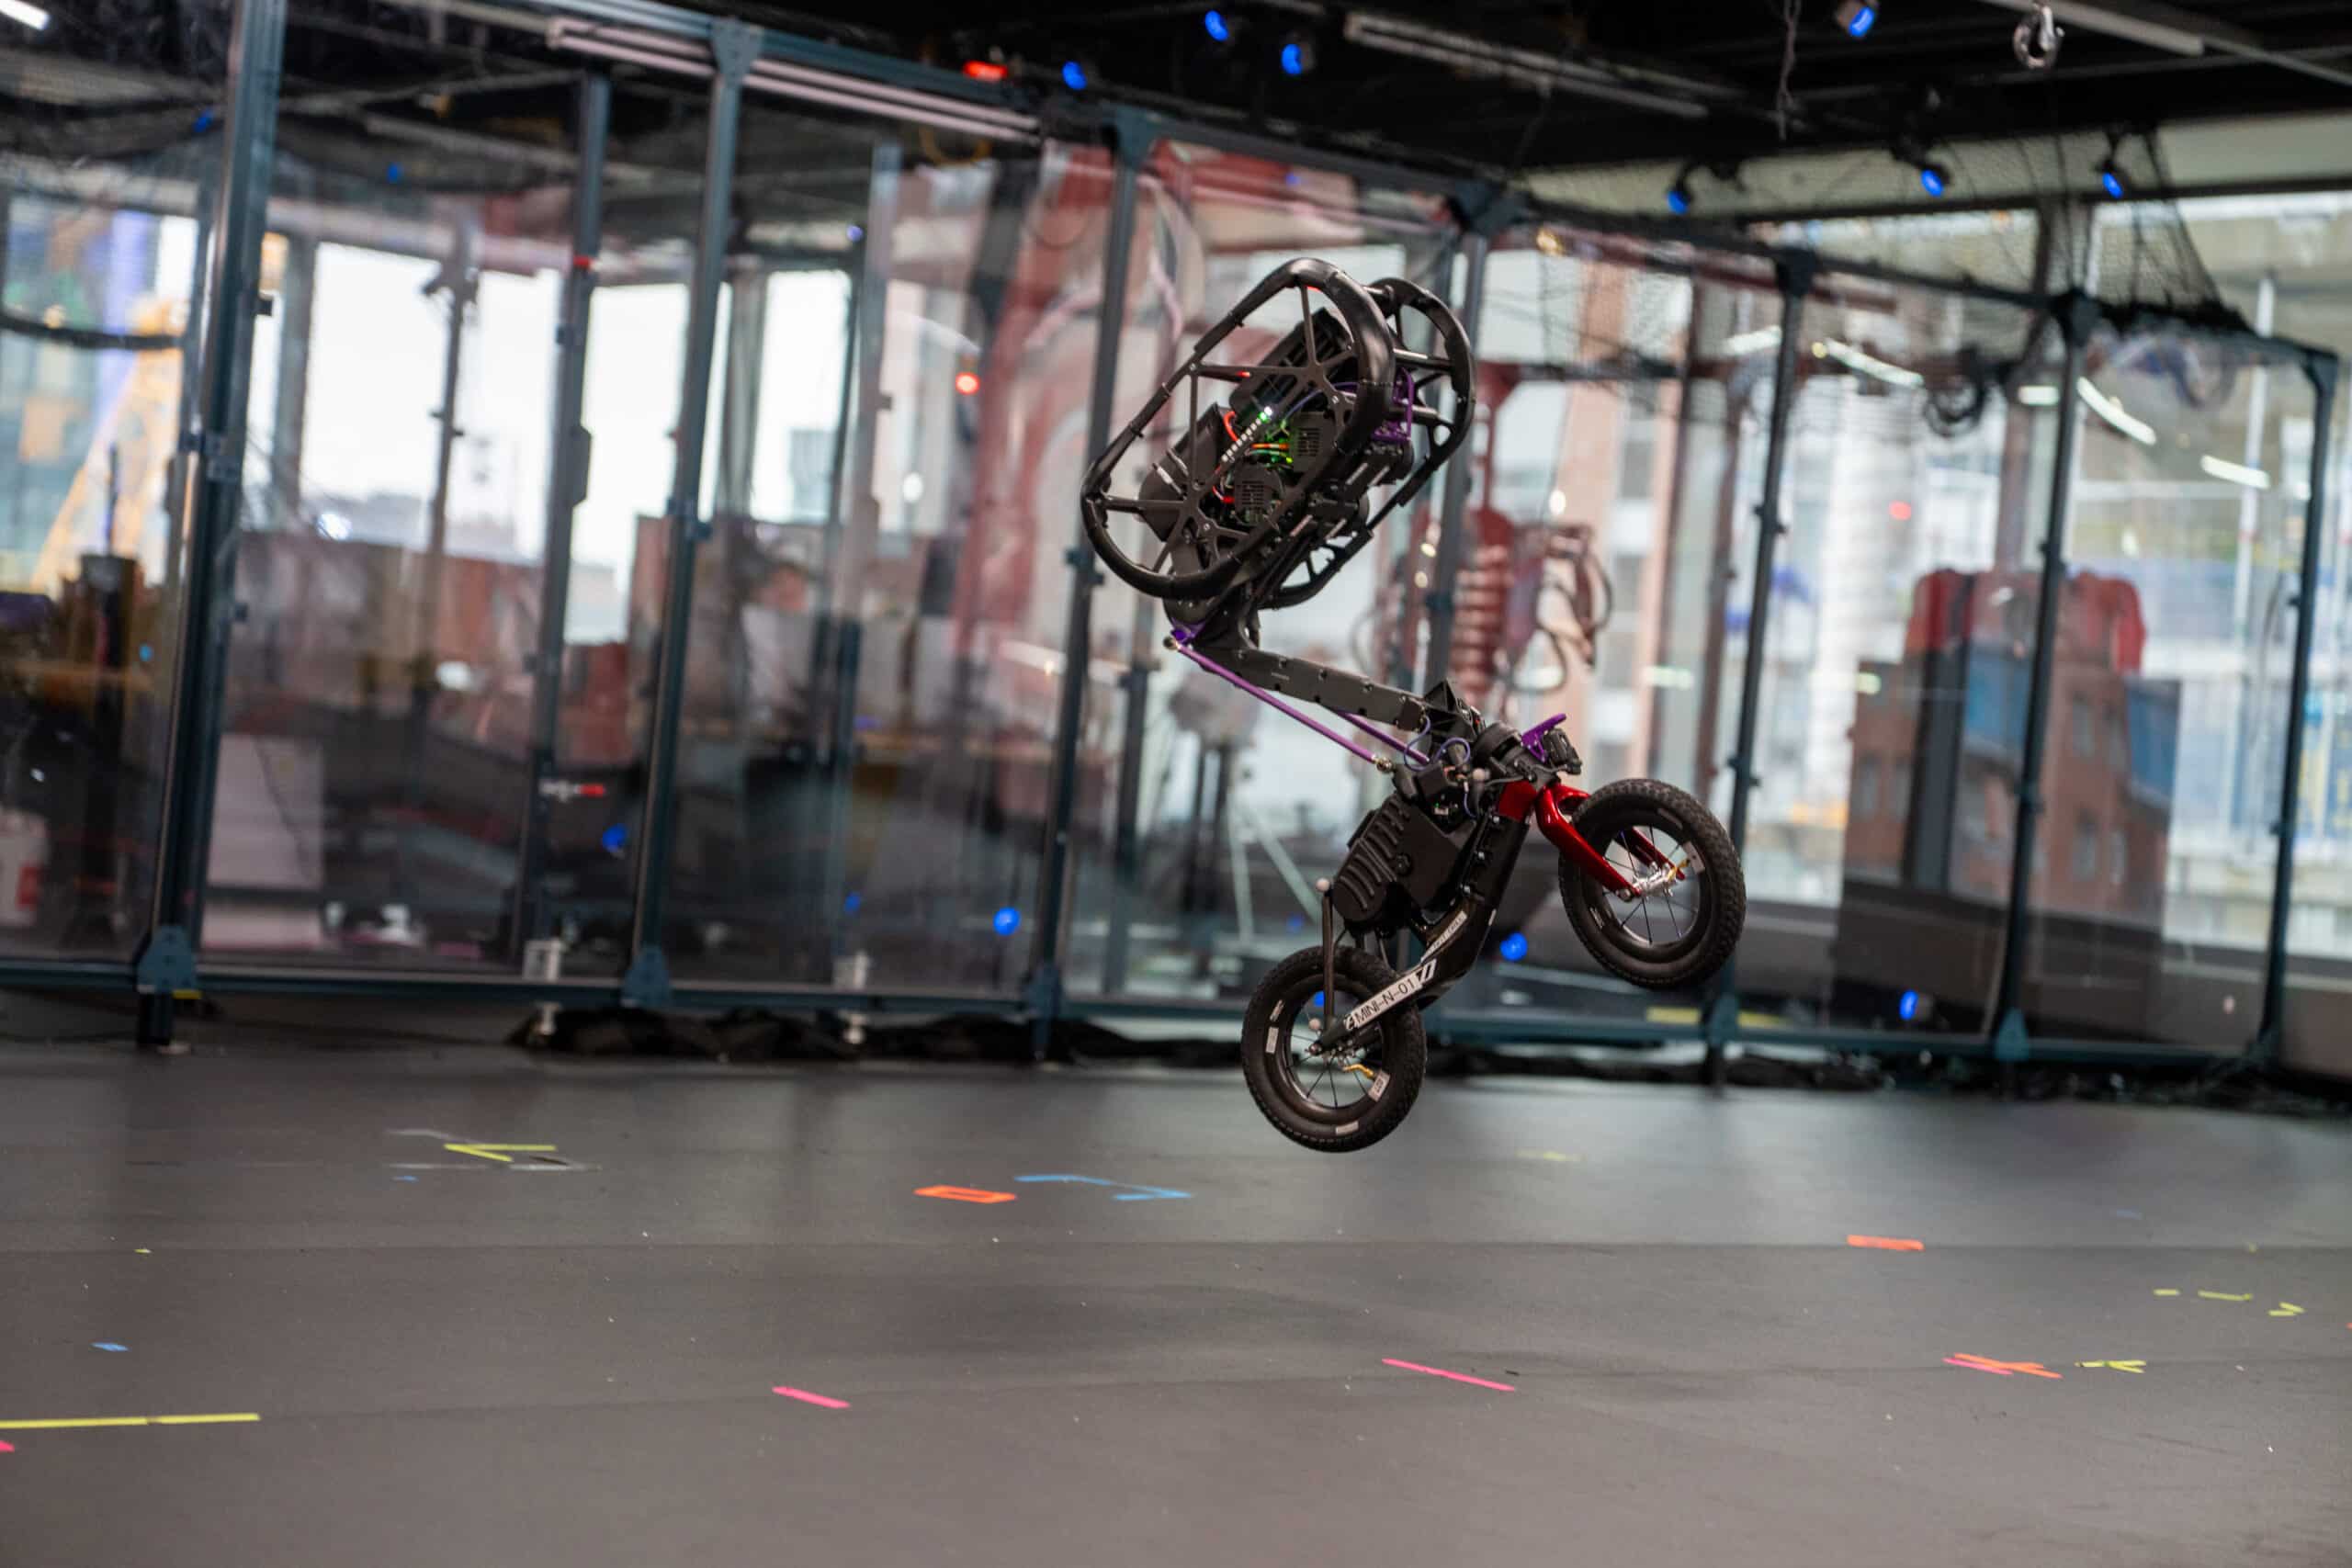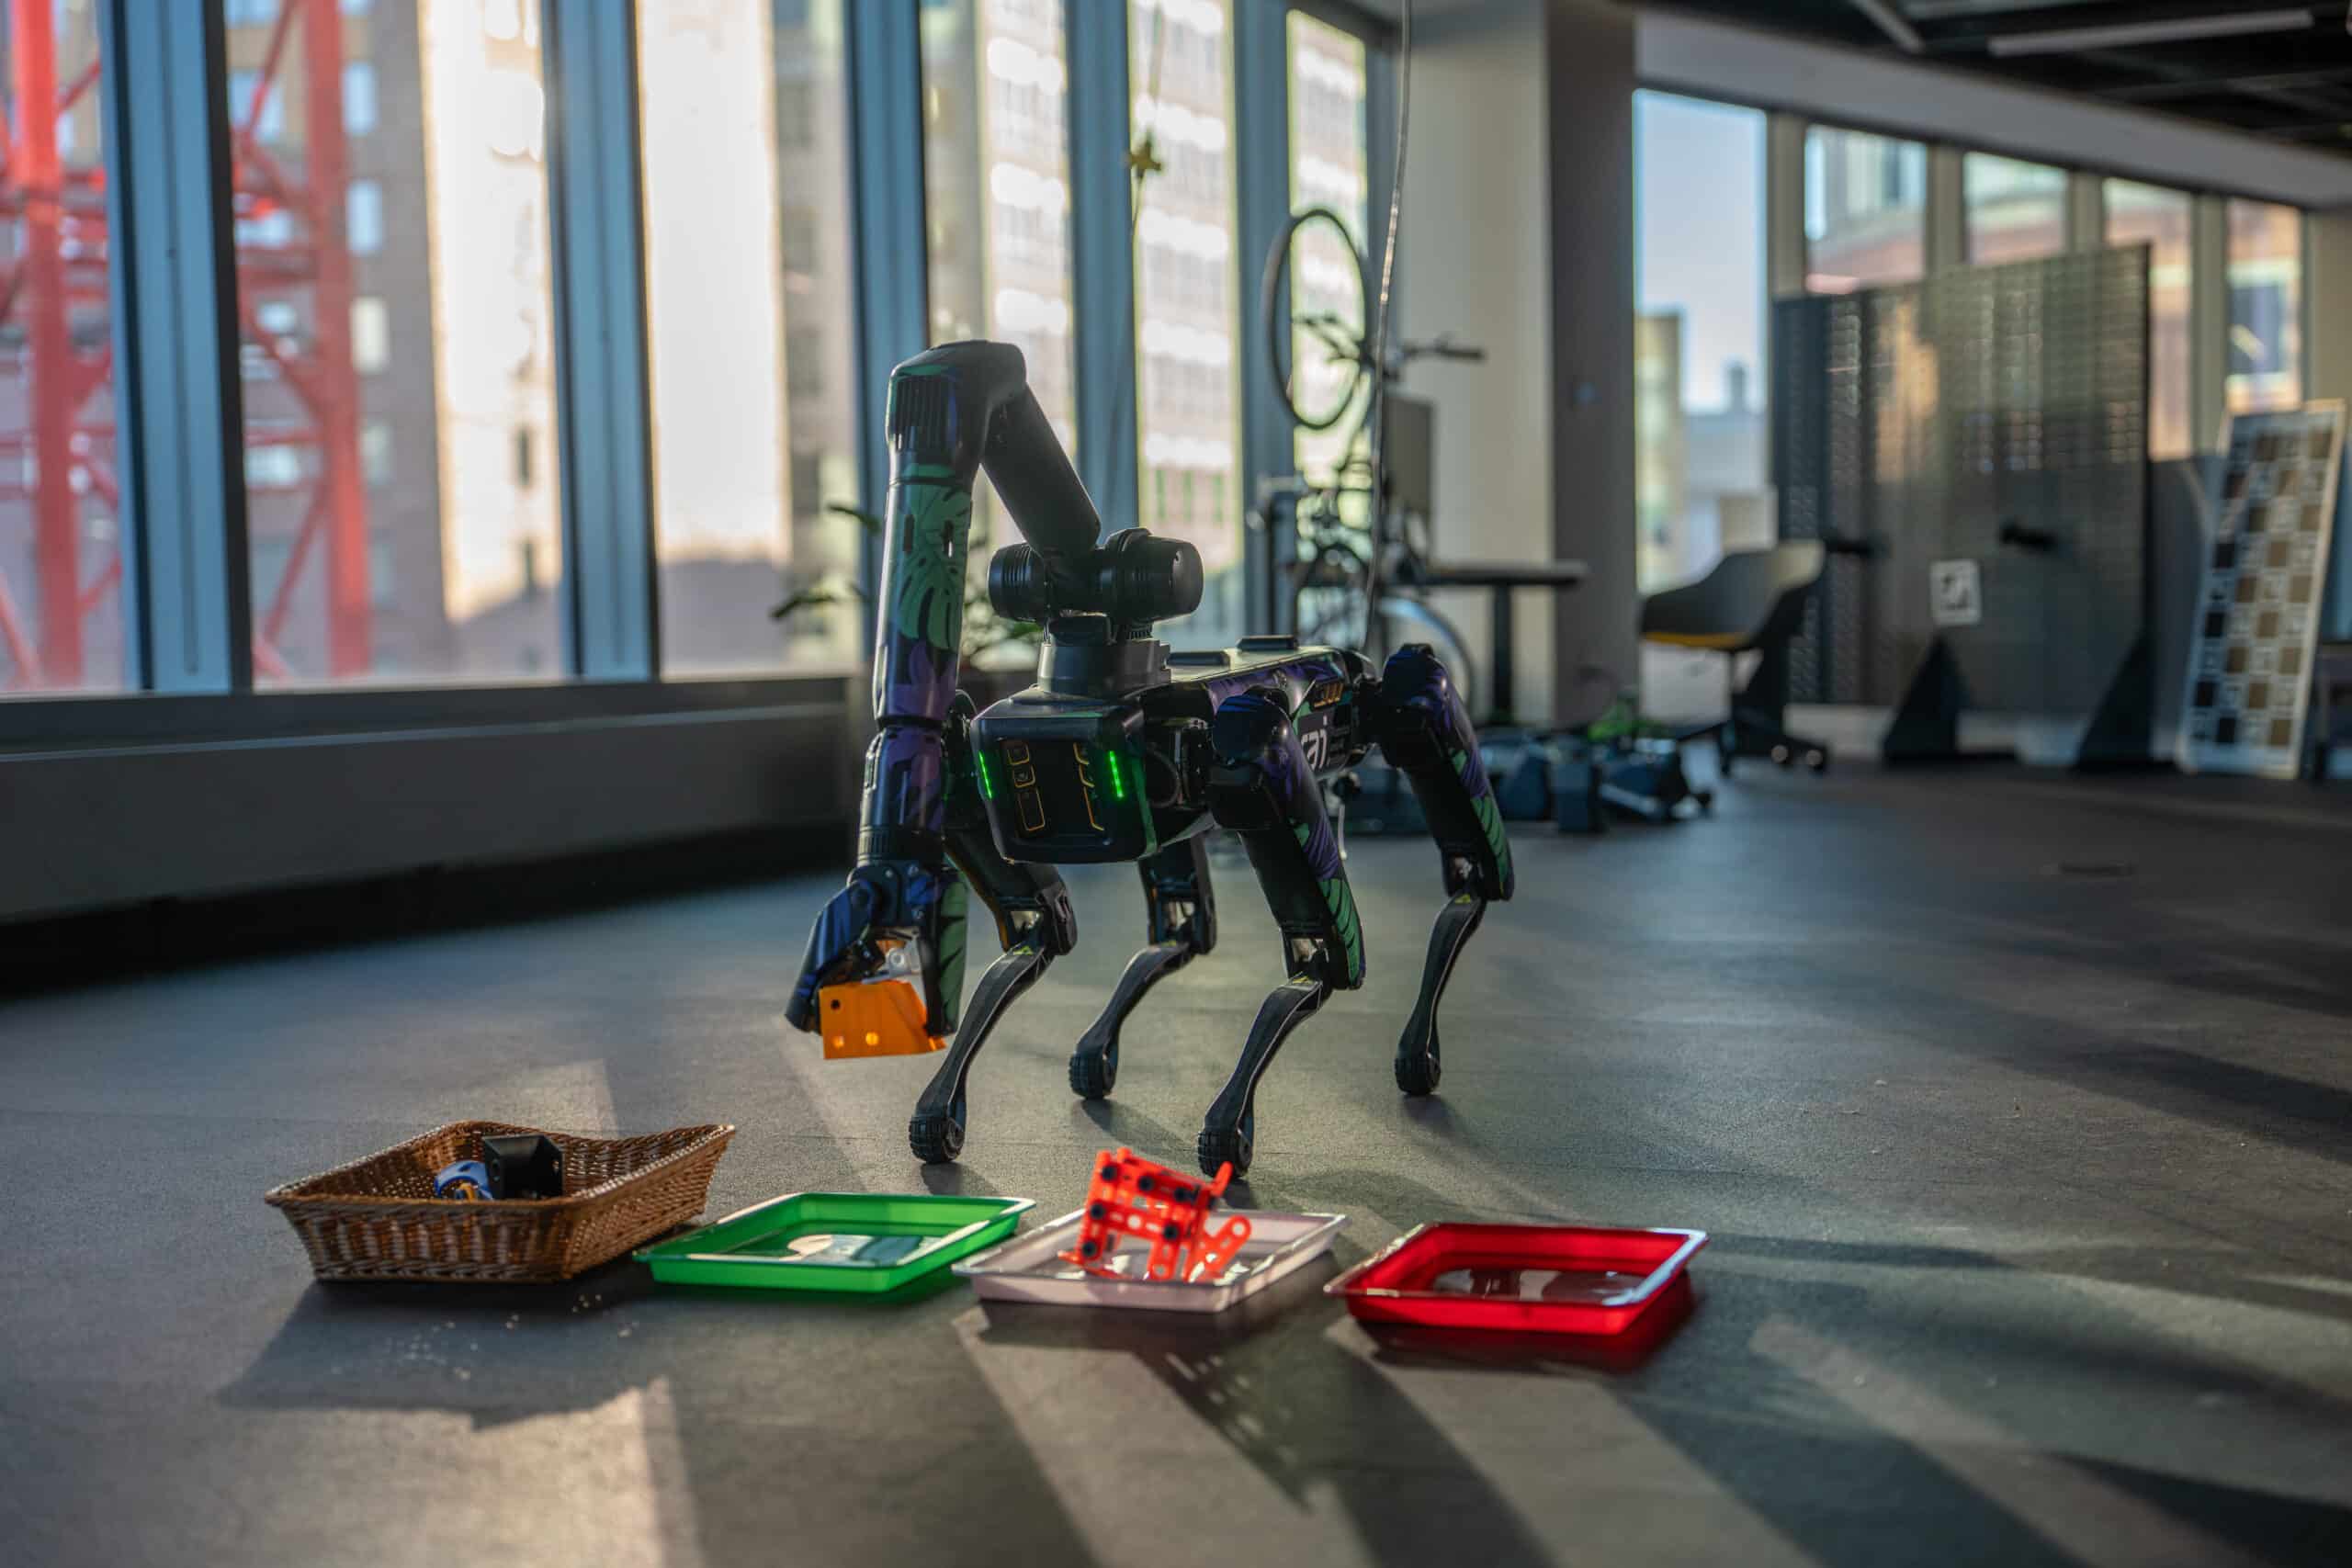
Automatically converting demos into labeled datasets to enable the rapid training of task-specific object detectors that outperform existing state-of-the-art VLMs.
Q2RL: Reinforcement Learning to Improve Beyond Behavior Cloning
Presented at RSS 2026, Q2RL (Q-Estimation and Q-Gating from Behavior Cloning for Reinforcement Learning) is a method that avoids catastrophic forgetting when transitioning from offline...